To keep the economics of distilling our own LLM sustainable, I spend most of my engineering time building and deploying 分离式系统.
The production rule is simple:
Do not route predictable work through an LLM.
I aim to ship about a dozen heavy 分离式系统 each week. Each one requires workflow analysis, pattern extraction, rule definition, and field validation before it goes 实时.
For the harder problems, I usually start with ChatGPT or Claude as a higher-level reasoning and research layer to shape the solution.
The pipeline then looks like this:
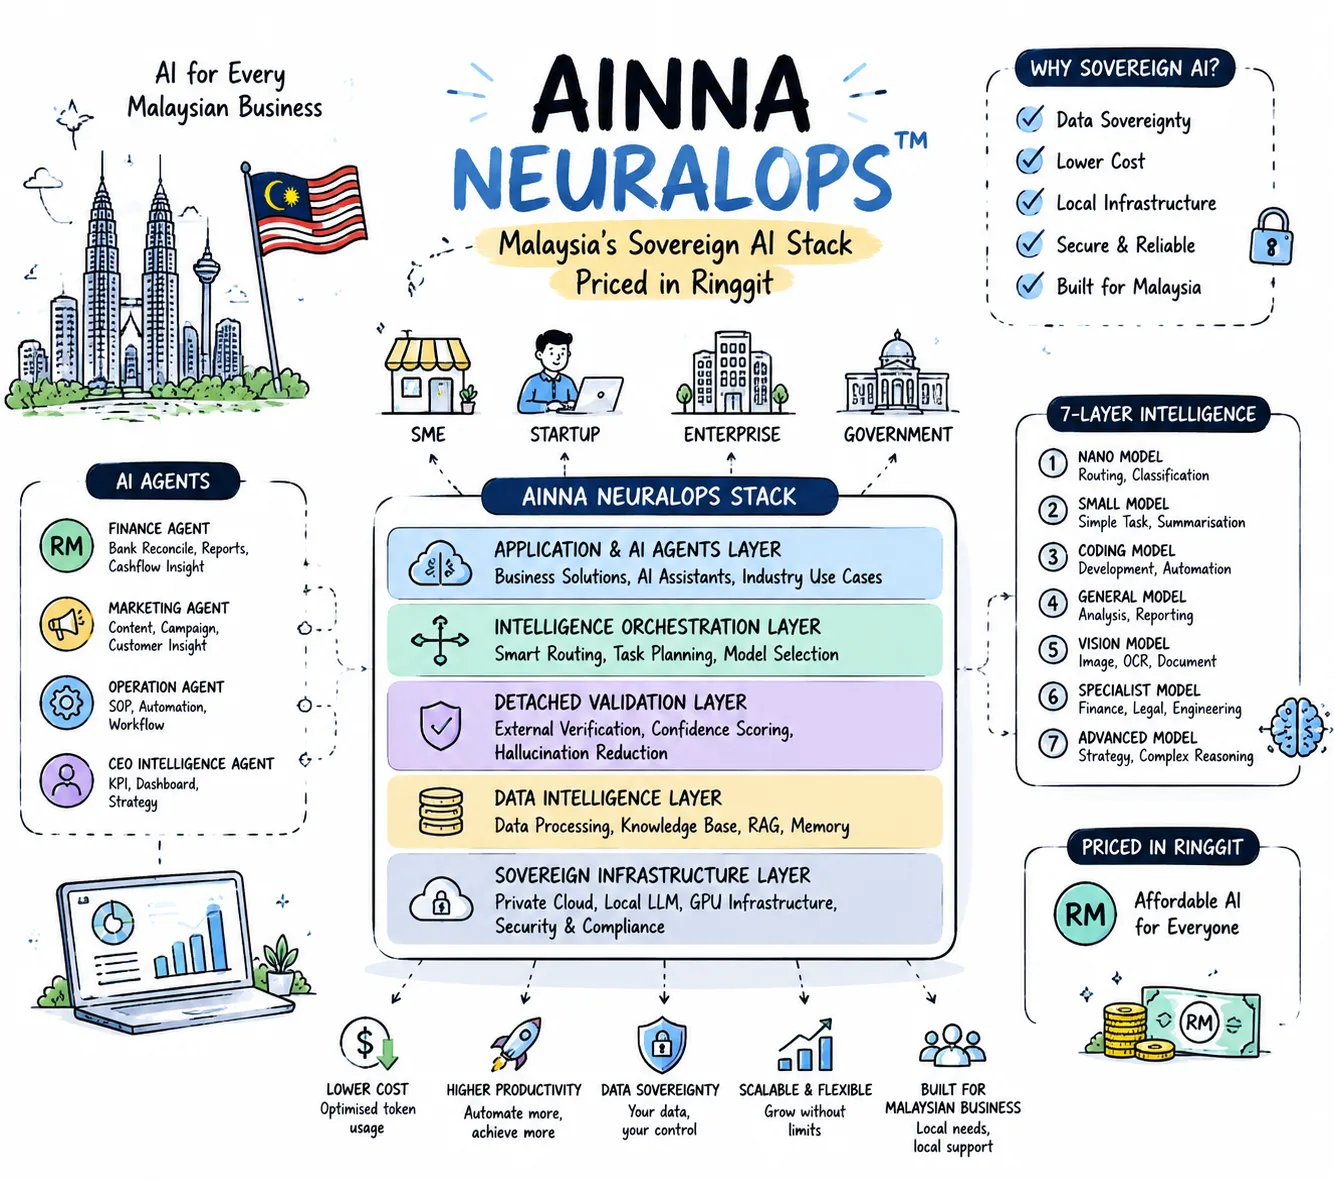
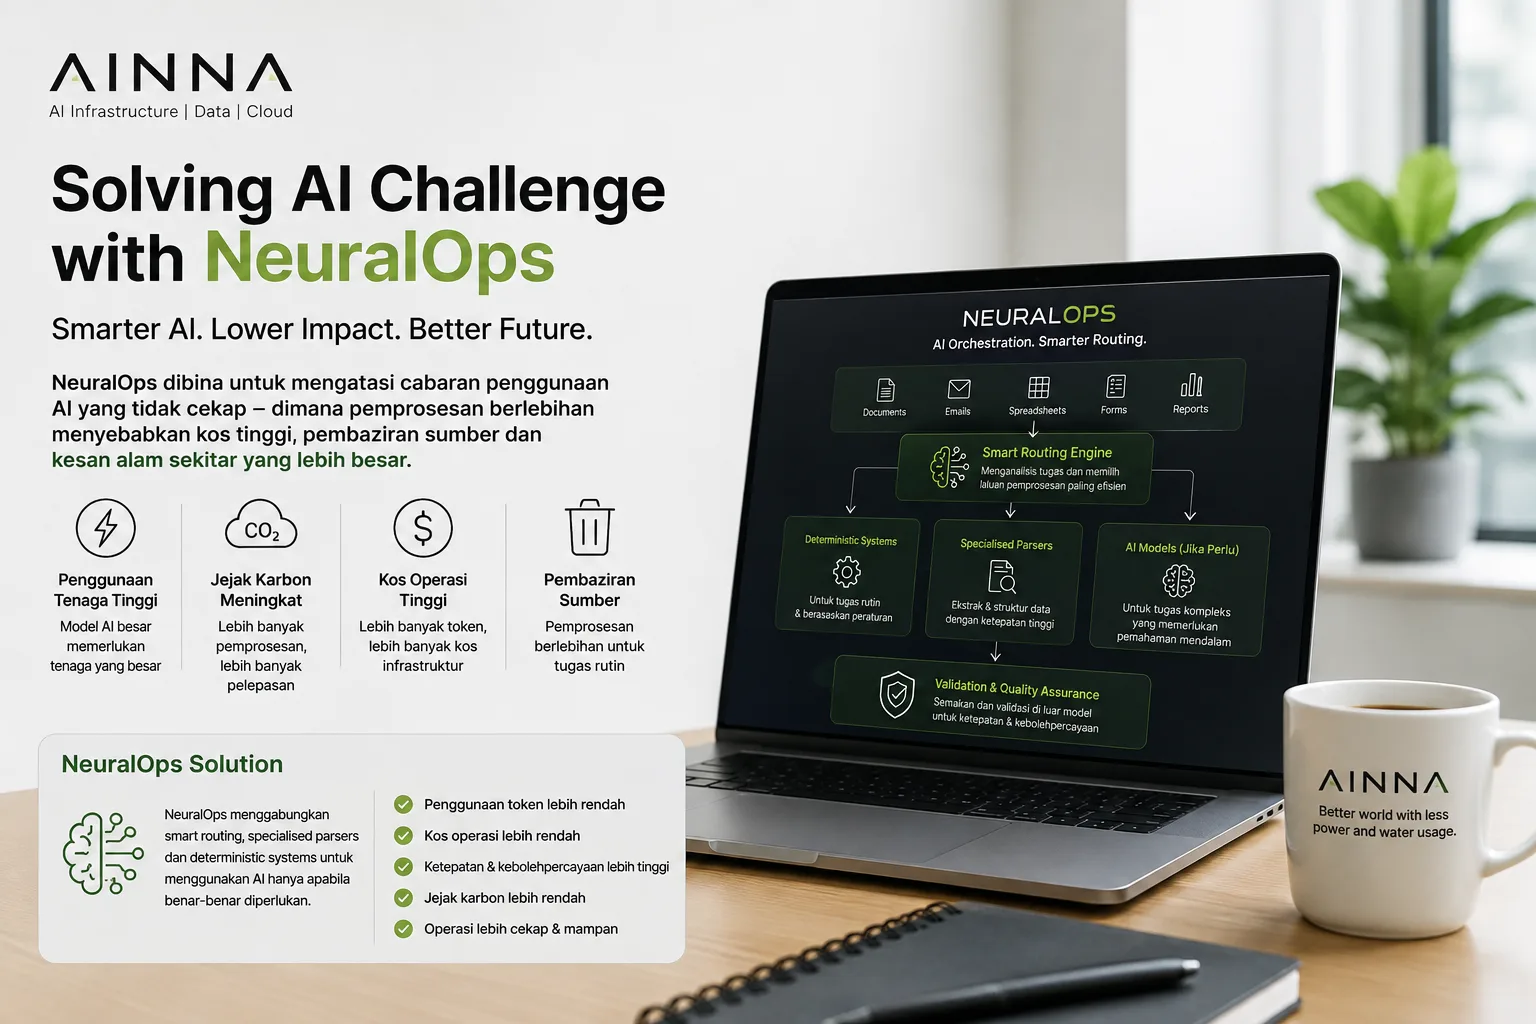
复杂 问题 → 研究 → 推理 → 蒸馏 → 确定性 Logic → 智能路由 → DeepSeek V4 Flash / Our Own LLM → 执行
The critical engineering decision is what happens after the deterministic logic stage.
If rules, parsers, validators, or structured logic can resolve the workload, the 独立系统 executes it directly.
If more reasoning is required, the workload is routed to DeepSeek V4 Flash as a cost-efficient external model.
For specialised, strategic, sensitive, or sovereignty-related workloads, we route the task to our own LLM models instead.
This is not about eliminating LLMs.
It is about routing work to the right processor at the right time.
确定性 logic first.
成本-efficient LLM when reasoning is required.
Our own LLM when specialised intelligence, control, or sovereignty matters.
This routing architecture is what makes the economics of owning our own models work.
The more workloads we detach from the LLM path, the lower our recurring token and inference spend.
The lower that spend becomes, the more budget we can redirect into model distillation, evaluation, infrastructure, and the broader development of our own LLM ecosystem.
That is the operating model behind AINNA NeuralOps.
#AINNA #NeuralOps #DetachedSystems #LLM #AIDistillation #SovereignAI #AIInfrastructure #DeepSeek #ChatGPT #Claude #EnterpriseAI #自动化


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
关于sovereignty-related的实际落地部分最吸引我。
总结部分让higher-level的重点更加清楚。
难得有人把成本-efficient LLM when reasoning讲得这么直白。 这个部分我还需要再想一下。
同意作者对pattern extraction, rule definition的判断,但执行起来还有难度。
收藏了,主要是为了our own LLM when specialised。
看第二遍才注意到parsers, validators, or structured logic的细节。
我特别喜欢evaluation, infrastructure, and the broader这一部分,内容没有把实施过程说得太简单。
我对strategic, sensitive, or sovereignty-related还有问题,但文章已经提供了很好的起点。
这篇文章把control, or sovereignty matters讲得比一般的AI介绍更具体。
文章对cost-efficient的结论比较平衡,不只是强调好处。 读完之后还有一些疑问。
视觉和结构让evaluation, infrastructure, and the broader的概念更容易掌握。
这篇内容让我更容易理解为什么cost-efficient值得关注。
cost-efficient这个说法我要拿回去跟同事讨论。
这篇文章适合团队用来开始讨论cost-efficient。