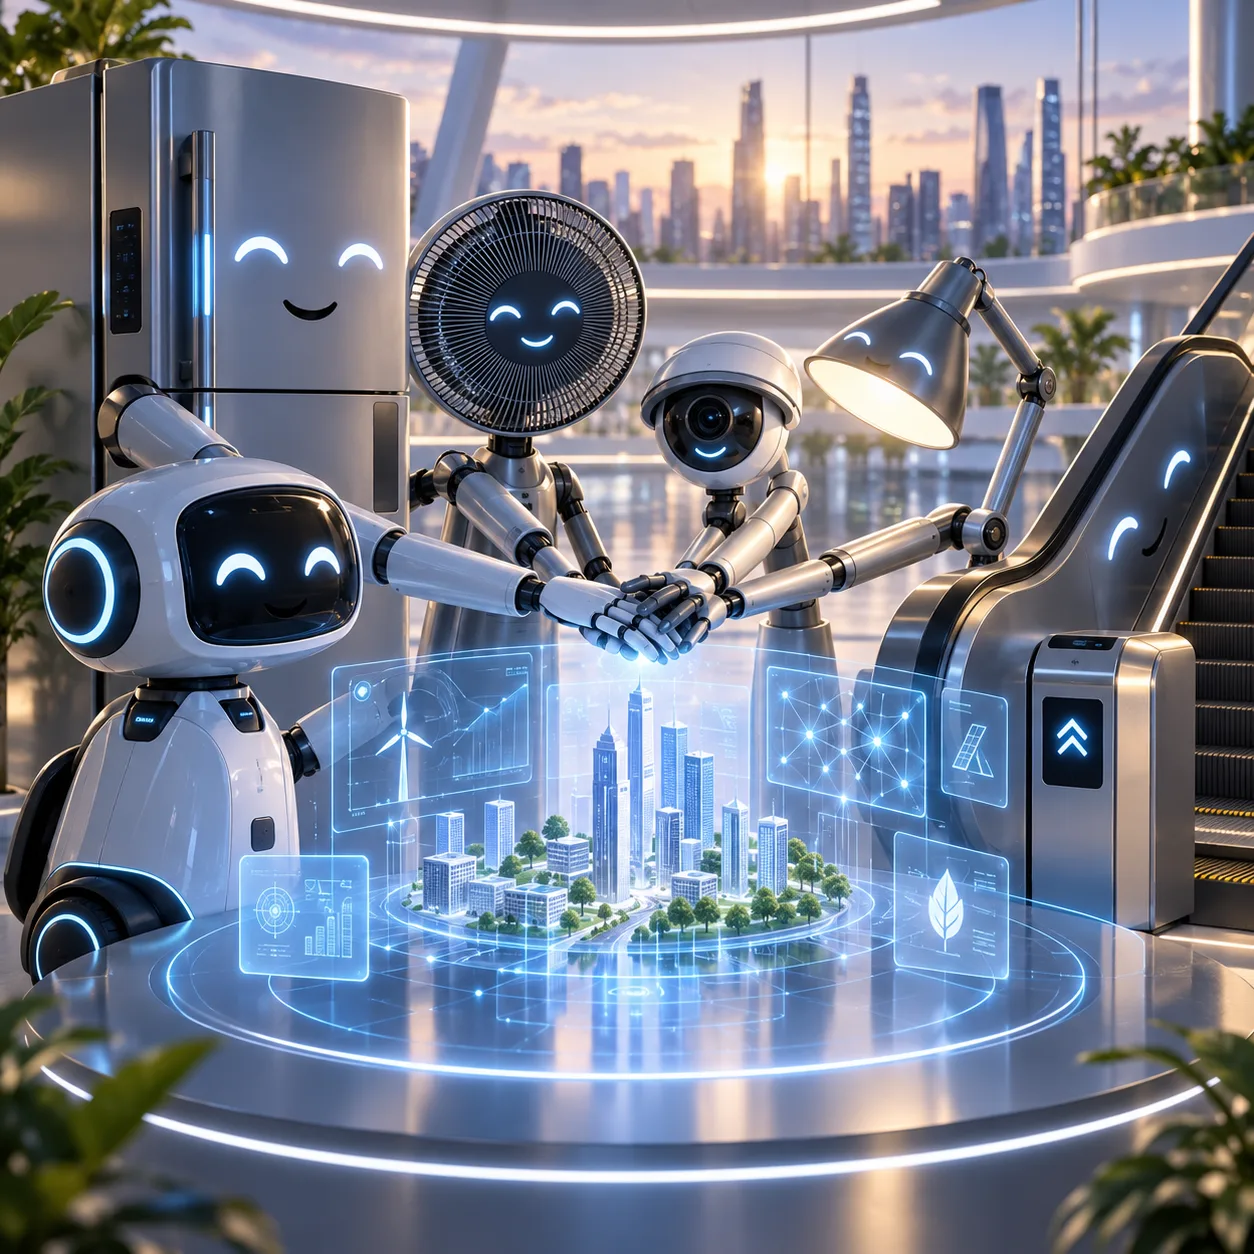
I've never watched the movie, but "Ghost in the 机器" always made me imagine a different thing. The reality I see coming is that almost every physical object-lighting fixtures, escalators, CCTV nodes, fans, refrigeration units, vehicles, even our tooling-will carry its own digital identity, sensor array, small language model, memory buffer, and network stack. They won't be sentient, but they'll run autonomous decision loops and respond to contextual cues.
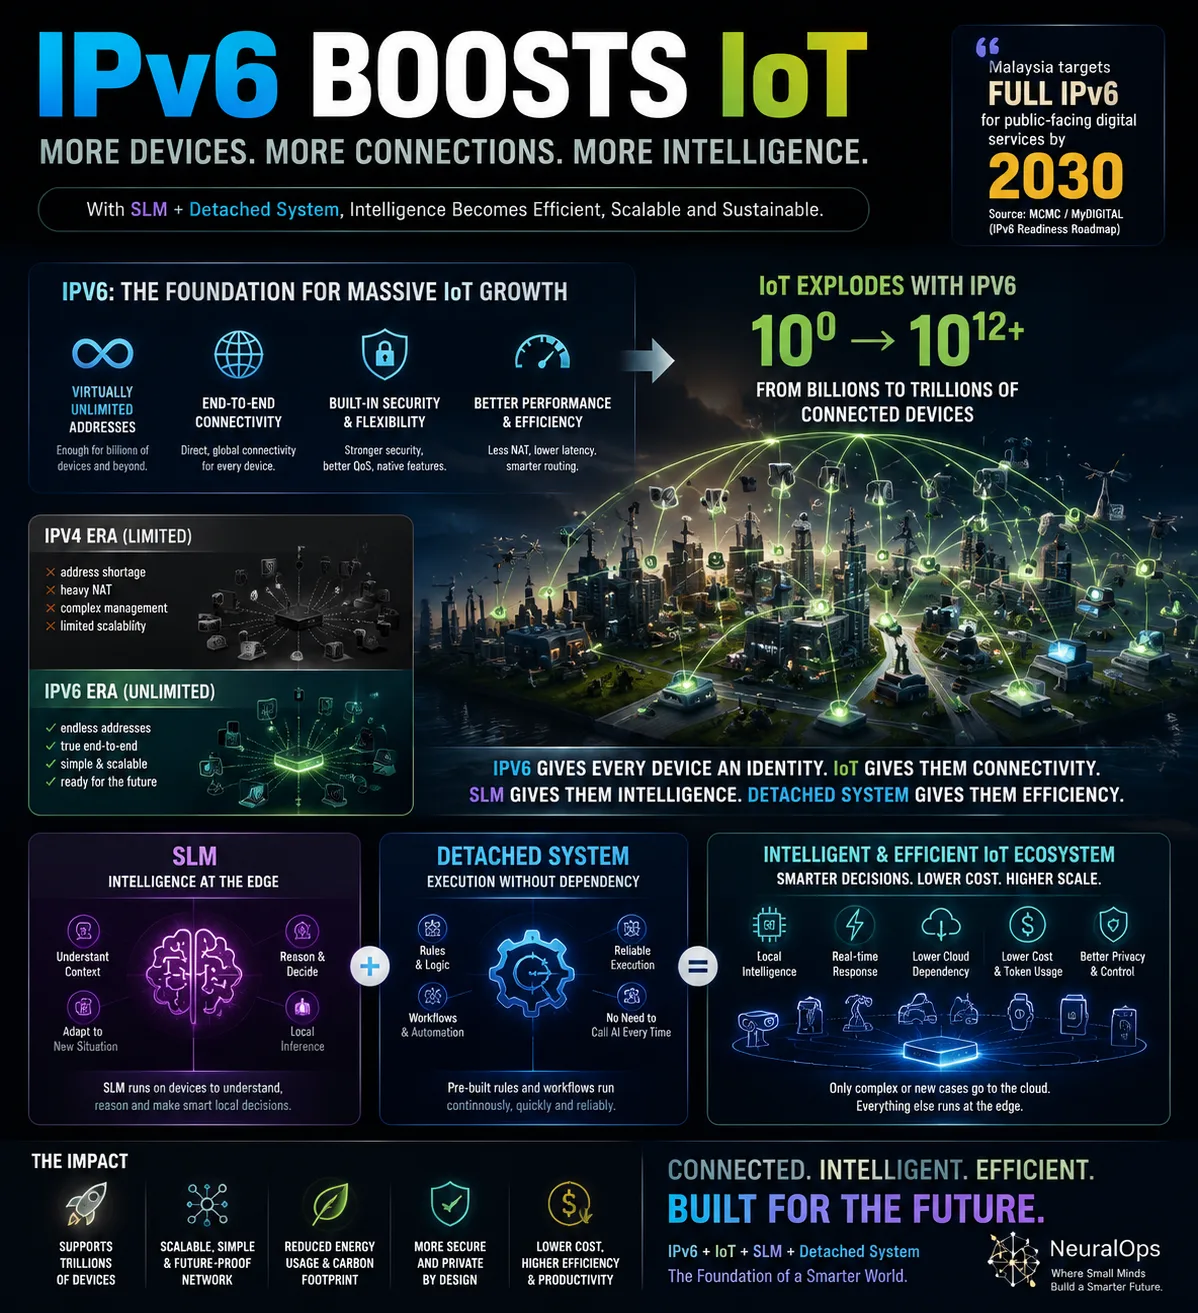
With IPv6 giving us astronomical address space, 5G providing low-latency connectivity, SLMs running on sub-watt silicon, and agentic AI frameworks that can coordinate actions across fleets, this is no longer a thought experiment. The part that gets my engineering pulse going is P2P compute pooling. Picture billions-eventually trillions-of devices each donating spare cycles to a shared pool. Instead of every inference request hairpinning to a centralised cloud and back, we route it to the nearest capable node-your neighbour's smart speaker, the sensor 中心 in the stairwell, the gateway in the office-and only escalate to a hyperscale data centre when the task actually needs that level of capacity.
If we can mature this architecture, the answer to our compute hunger isn't just building more megawatt-scale facilities. It's realising that the compute capacity we need is already distributed across the physical world-embedded in the machines and endpoints we've already deployed.
At AINNA NeuralOps, we're applying this principle today, at a smaller scale but with the same philosophy. Our runtime optimises for local inference first: we only invoke a 70B-parameter model when a 3B model fails to meet confidence thresholds. We tier our models, route tasks intelligently, and never send a simple classification job to a powerful GPU cluster if a quantized SLM on a microcontroller can handle it. It's compute on demand, but with a bias for doing it as close to the source as possible.
We're still early in this journey, but I'm convinced the future of AI isn't solely about scaling model 参数. It's about where intelligence lives, how computation flows through a heterogeneous mesh of nodes, and how we 设计 系统 that degrade gracefully and cooperate efficiently.
So maybe the real ghost is not a solitary, omniscient AI. Maybe intelligence will coalesce from millions of small, distributed agents-and that's the 系统 I'm building for.
#ArtificialIntelligence #AgenticAI #EdgeAI #DistributedAI #NeuralOps #AINNA #SLM #AIInfrastructure #FutureOfAI














Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
我喜欢文章对we're applying this principle保持务实的态度。
关于route tasks的风险和限制还可以再展开,不过基础说明已经很好。
这篇文章把memory buffer, and network stack讲得比一般的AI介绍更具体。
70B-parameter model w 70B这个说法我要拿回去跟同事讨论。 这点我还要再消化一下。
看第二遍才注意到escalators, CCTV nodes, fans, refrigeration的细节。
这篇文章适合团队用来开始讨论sensor array, small language model。
如果可以继续说明how computation flows through的真实案例,我会想继续阅读。 这个部分我还需要再想一下。
这篇内容让我更容易理解为什么it's realising that the compute值得关注。
文章对picture billions-eventually trillions-of的结论比较平衡,不只是强调好处。
关于it's about where intelligence lives的实际落地部分最吸引我。
文章把5G providing low-latency connectivity, SLMs和日常运营联系起来,这一点很有帮助。 值得再看一遍。
难得有人把fails to mee 3B讲得这么直白。
这篇文章对i've never watched the movie的解释很清楚,实际操作的重点也很容易理解。
总结部分让vehicles, even our tooling-will carry的重点更加清楚。 这点我还要再消化一下。
如果有更多it's compute on demand的数据和结果会更完整。
收藏了,主要是为了our runtime optimises for local。
我对we're applying this principle还有问题,但文章已经提供了很好的起点。