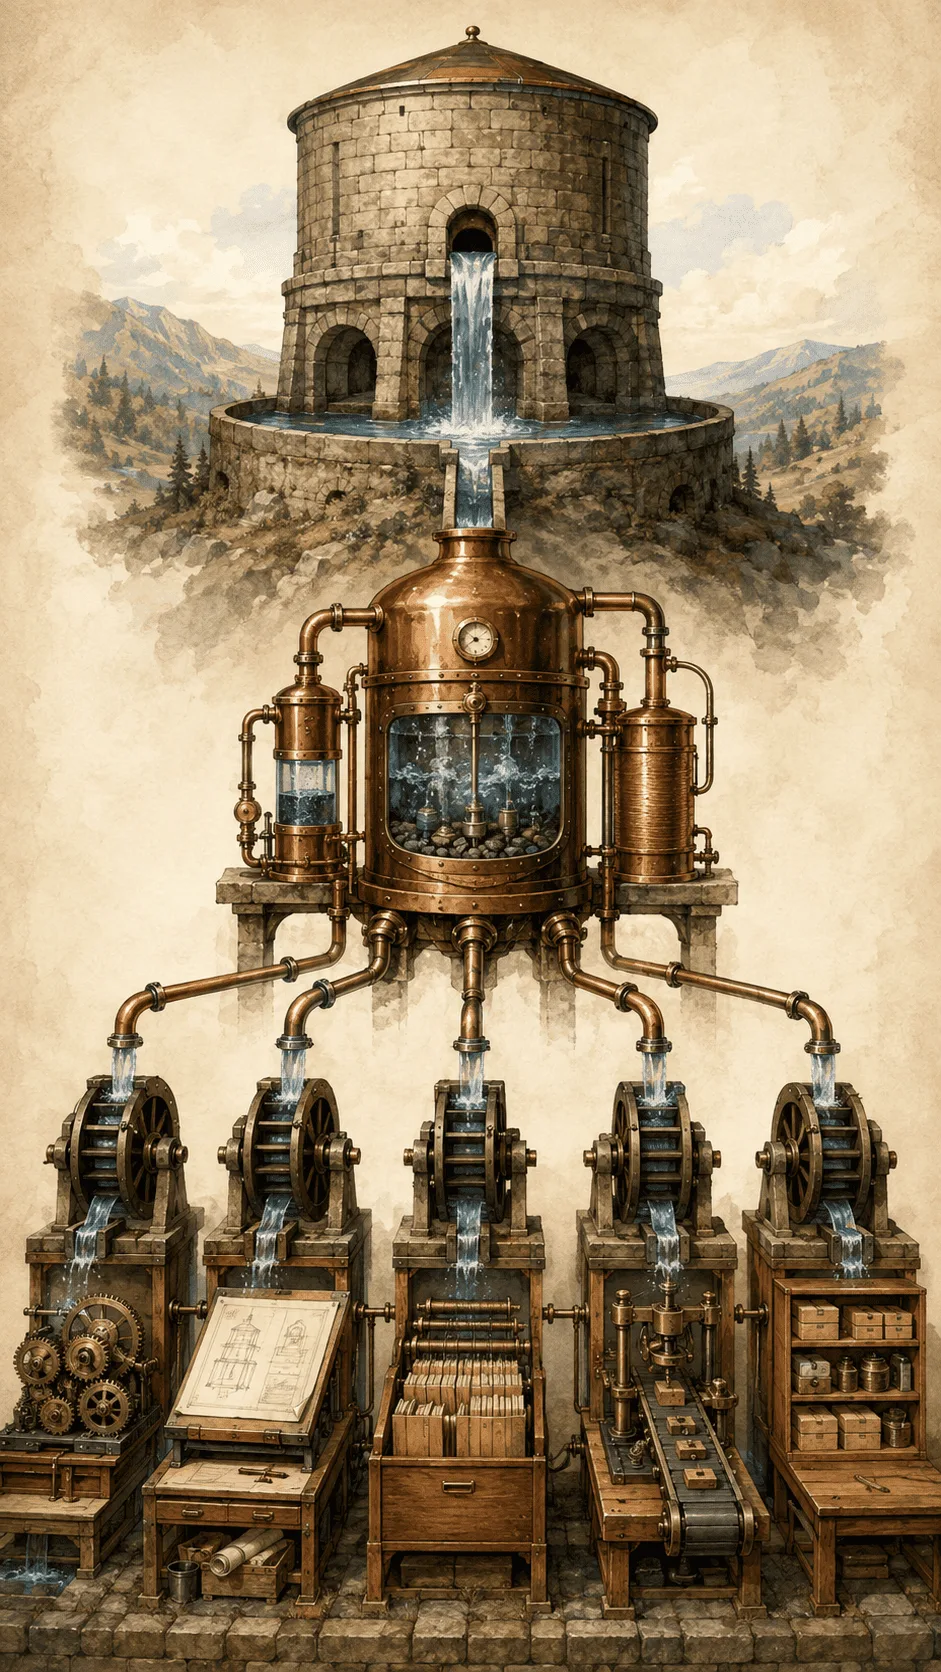
OpenAI continues to push the cost of advanced intelligence lower, while models such as DeepSeek are becoming increasingly efficient for coding and agentic workloads.
In our own development, we use OpenAI as a teacher model for distillation.
The 目标 is not to send every operational task permanently to the most 高级模型.
We use stronger models where their intelligence creates the most value:
训练. 推理. Evaluation. 蒸馏.
然后 we move repetitive and specialised workloads toward more efficient models, local models, specialised 系统 and deterministic processes.
One thing I have noticed during 系统 development is the difference in token behaviour.
Some models can consume very large amounts of context during long coding and agentic tasks.
With DeepSeek, particularly for development workloads, we have been able to run substantial tasks without constantly reaching the token ceiling.
This leads to an important question:
The best AI model is not necessarily the model you should use for every task.
A better architecture may look like this:
Advanced OpenAI model → Teacher / 蒸馏
高效 LLM / SLM → Specialised intelligence
独立系统 → Repetitive deterministic workloads
智能路由 → 决定 which layer should handle each task
This is where AI economics becomes interesting.
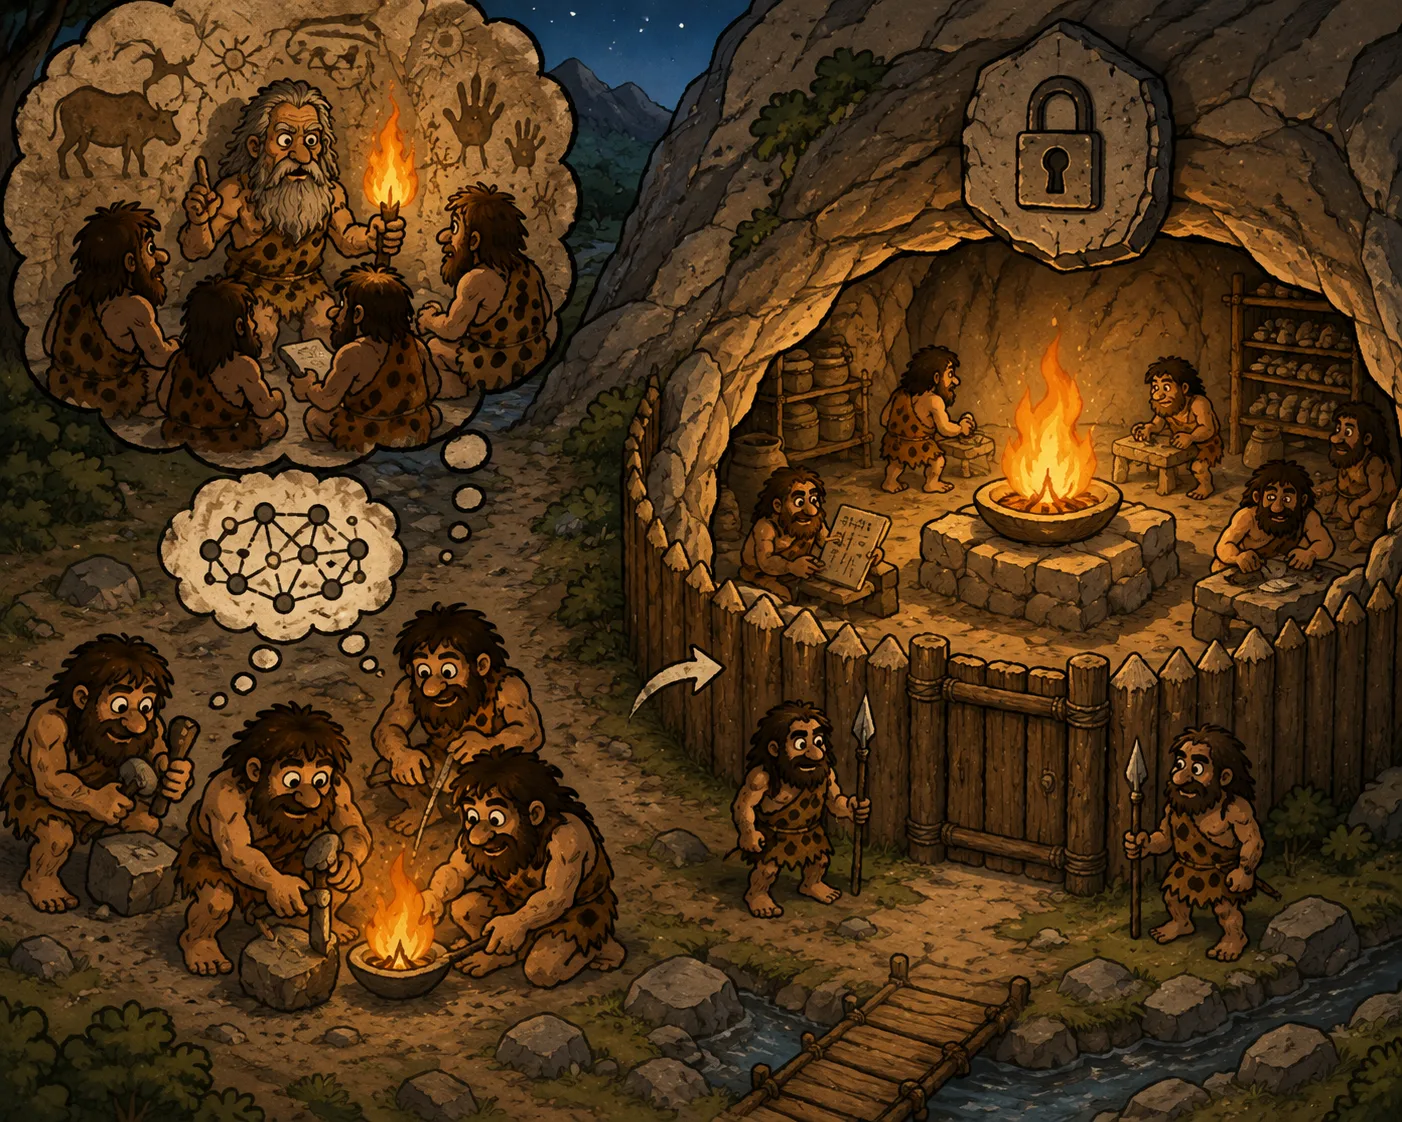
As frontier intelligence becomes cheaper, we can use it to create and improve smaller specialised intelligence rather than continuously paying frontier-model costs for every operation.
For 中小企业, this could fundamentally change the economics of AI adoption.
The competitive advantage will not come from simply having access to the biggest model.
It will come from knowing:
which model to use, when to use it, what to distill, and what should not use an LLM at all.
That is the direction we are building toward at AINNA NeuralOps.
#ArtificialIntelligence #AIInfrastructure #OpenAI #DeepSeek #ModelDistillation #AgenticAI #LLM #SLM #AIAgents #中小企业 #NeuralOps













Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
如果还有这段说明的后续,我会继续读。 这点我还要再消化一下。
这篇文章对frontier-model的解释很清楚,实际操作的重点也很容易理解。
我喜欢文章对蒸馏.然后 we move repetitive保持务实的态度。
同意作者对particularly for development workloads的判断,但执行起来还有难度。
我会把openAI continues to push这一段分享给需要了解技术的同事。
这篇文章适合团队用来开始讨论local models, specialised 系统。
收藏了,主要是为了what to distill。
文章把particularly for development workloads和日常运营联系起来,这一点很有帮助。 这个部分我还需要再想一下。