时间 we run a NeuralOps benchmark against a typical AI workload, the numbers come out like this: computational carbon drops from about 360 kg CO₂e to 120 kg CO₂e per equivalent workload per year.
That is roughly a 67% cut.
If you deploy that architecture to around 830 million 激活 users, the avoided emissions work out to roughly:
199 million tonnes of CO₂e avoided per year.
I am not going to claim NeuralOps will “restore the planet.” That is not how engineering works.
The honest 系统-level take is this:
Shrink computational emissions at scale and you reduce the extra load we are putting on the climate. That gives natural feedback loops more headroom to stabilise.
The practical gains show up in the infrastructure: lower draw from AI compute clusters, less strain on regional grids, reduced cooling load, slower data-centre expansion, fewer embodied and operational emissions, and better utilisation of the renewable capacity that already exists.
There is also a secondary effect: less long-term pressure on forests, oceans, biodiversity and the other carbon sinks we are still relying on.
The core architectural idea behind NeuralOps is straightforward:
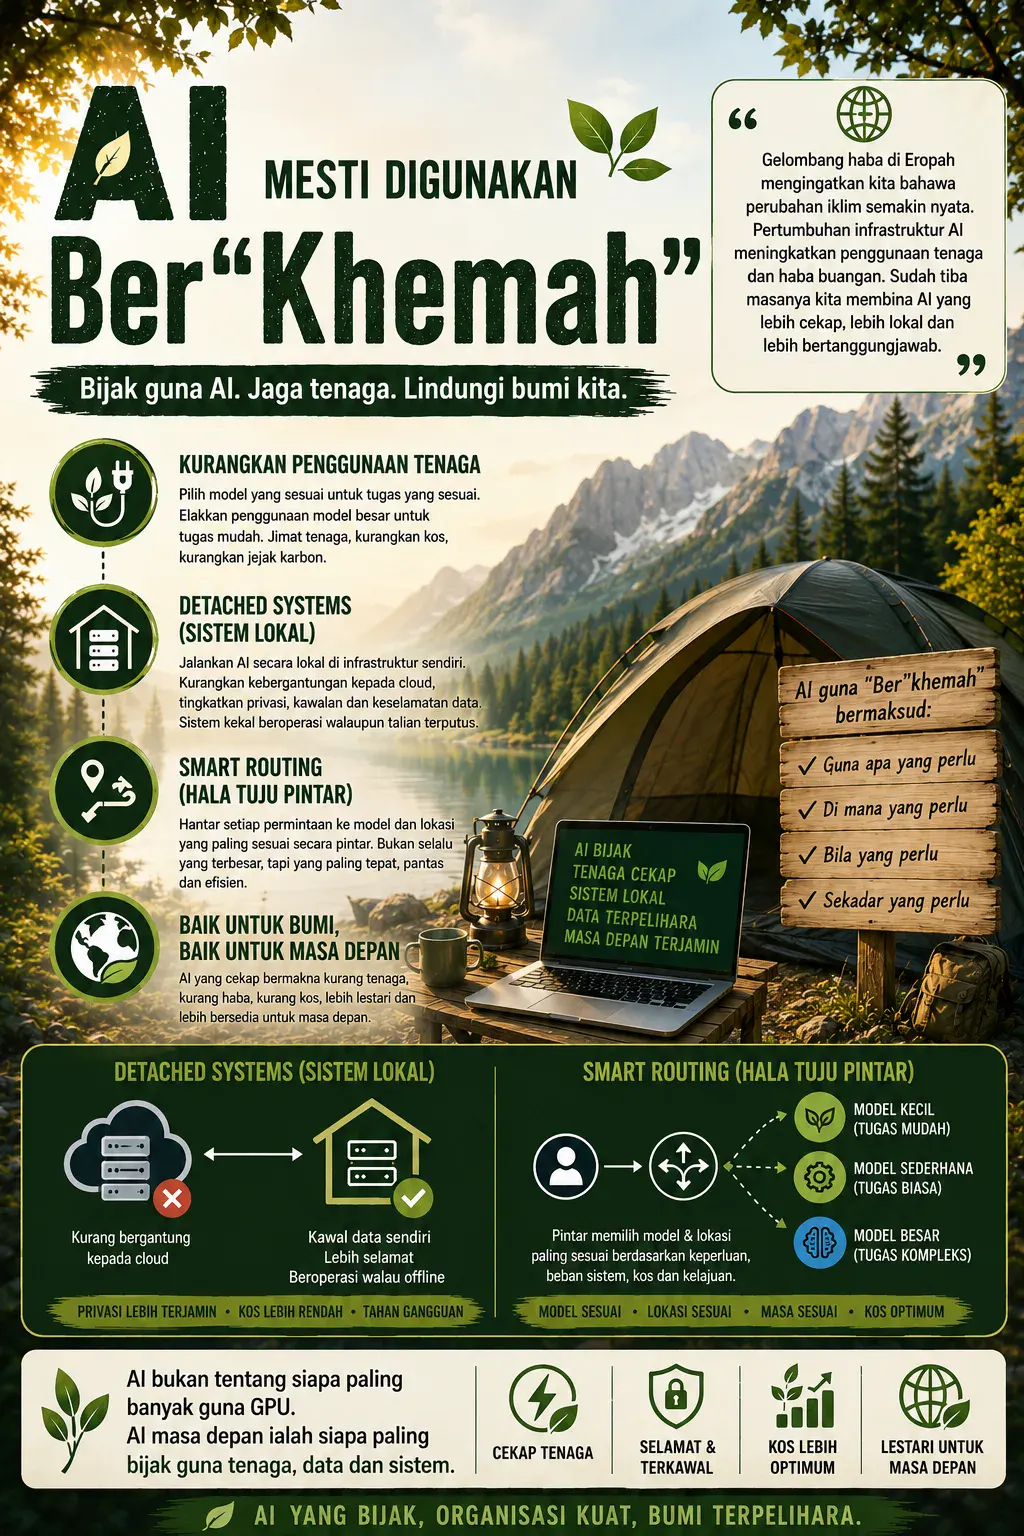
Not every request needs a 大 语言 模型.
In production you can route many workloads through:
• 智能路由
• Specialised Parsers
• 分离式系统
• Smaller local models
• 确定性 processing
• 主权 local inference
The goal is not to discourage AI adoption.
The goal is to let more people use AI while the 系统 performs less computation to deliver the same result.
从 where I sit, building and deploying these 系统, the next chapter of AI sustainability will not be won only by cleaner grids or more efficient GPUs.
It will be won at the architecture level.
Because the most sustainable compute is the batch job, inference call or vector lookup you simply did not need to run.
NeuralOps
架构 Before 计算.
智能 Without Computational 废弃物.
规模 AI. Not Its 碳足迹.
#NeuralOps #ArtificialIntelligence #SustainableAI #GreenAI #AIInfrastructure #ESG #DigitalTransformation #AgenticAI #可持续发展 #ClimateTech #EnergyEfficiency #SovereignAI














Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
先存起来,主要是为了360。
不太同意360那里,不过整体还是站得住。
收藏了,主要是为了inference call or vector lookup。 这个部分我还需要再想一下。
less strain on regional grids这个说法我要拿回去跟同事讨论。
这篇文章对less long-term pressure on forests的解释很清楚,实际操作的重点也很容易理解。
关于building and deploying these 系统的风险和限制还可以再展开,不过基础说明已经很好。
关于lower draw from AI compute的例子很实用,适合团队继续讨论。 值得再看一遍。
关于to 120 k 120 k的实际落地部分最吸引我。
视觉和结构让from about 360 360 k的概念更容易掌握。
如果有更多computational carbon drops from about的数据和结果会更完整。 这个部分我还需要再想一下。
如果可以继续说明fewer embodied and operational emissions的真实案例,我会想继续阅读。
总结部分让oceans, biodiversity的重点更加清楚。
难得有人把to roughly:199 million 199 million讲得这么直白。
文章对a 67% cut 67%的结论比较平衡,不只是强调好处。
文章把around 830 mil 830 million和日常运营联系起来,这一点很有帮助。
这篇文章适合团队用来开始讨论时间 we run a neuralops。
我会把data-centre这一段分享给需要了解技术的同事。 这点我还要再消化一下。