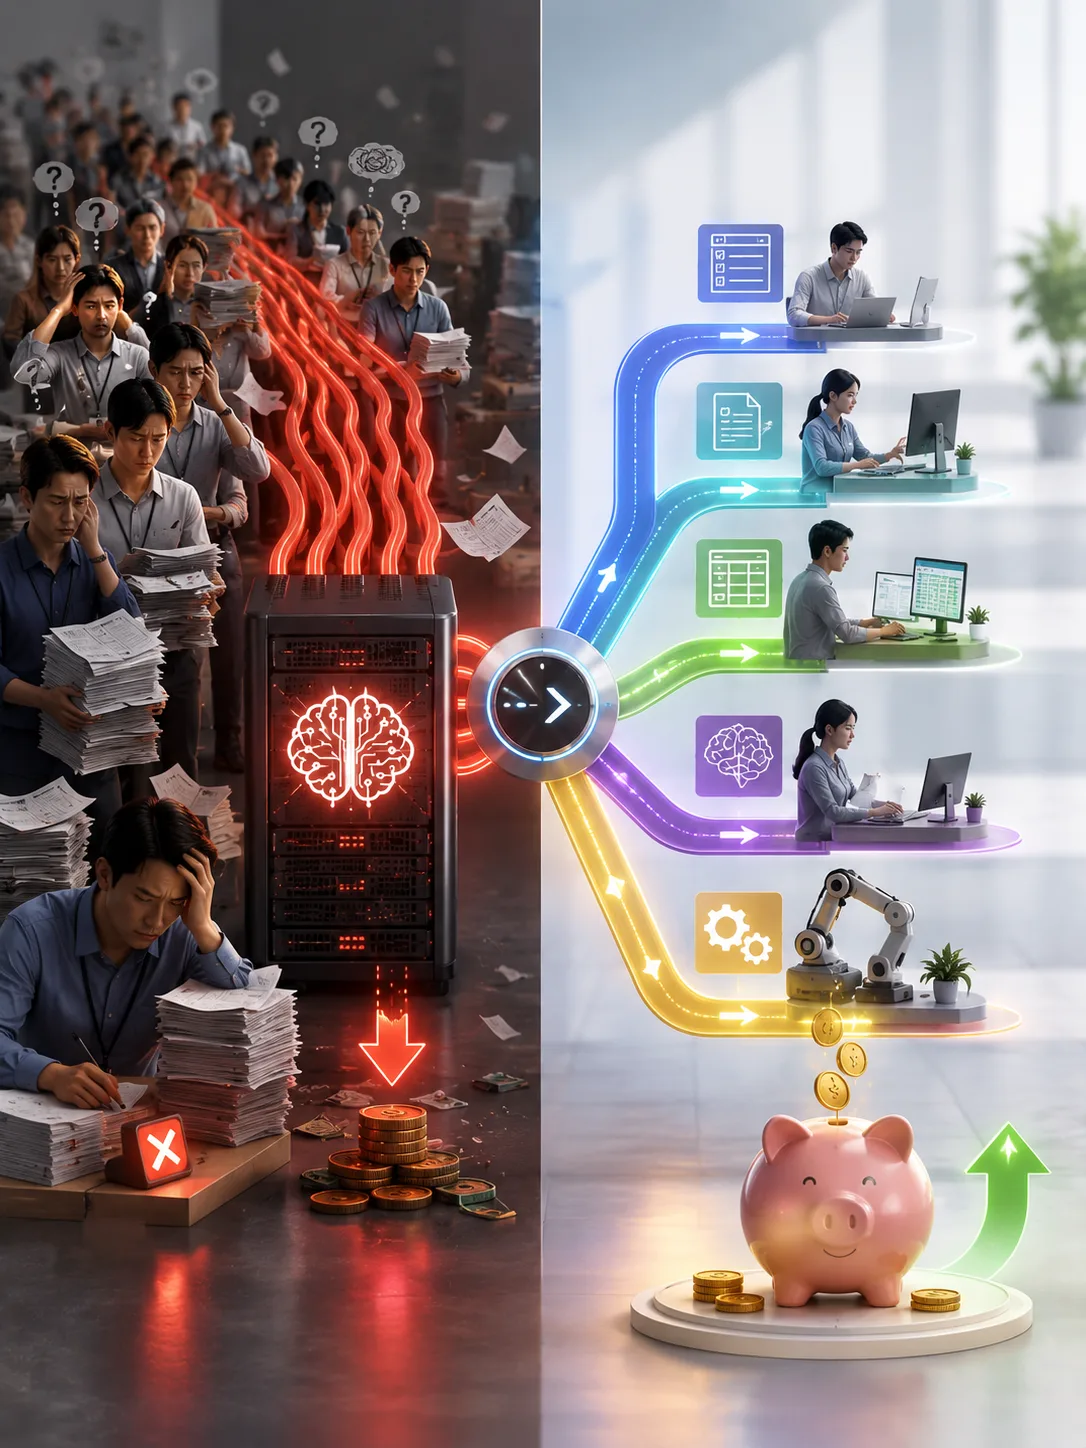
In production, not every request needs a foundation model behind it.
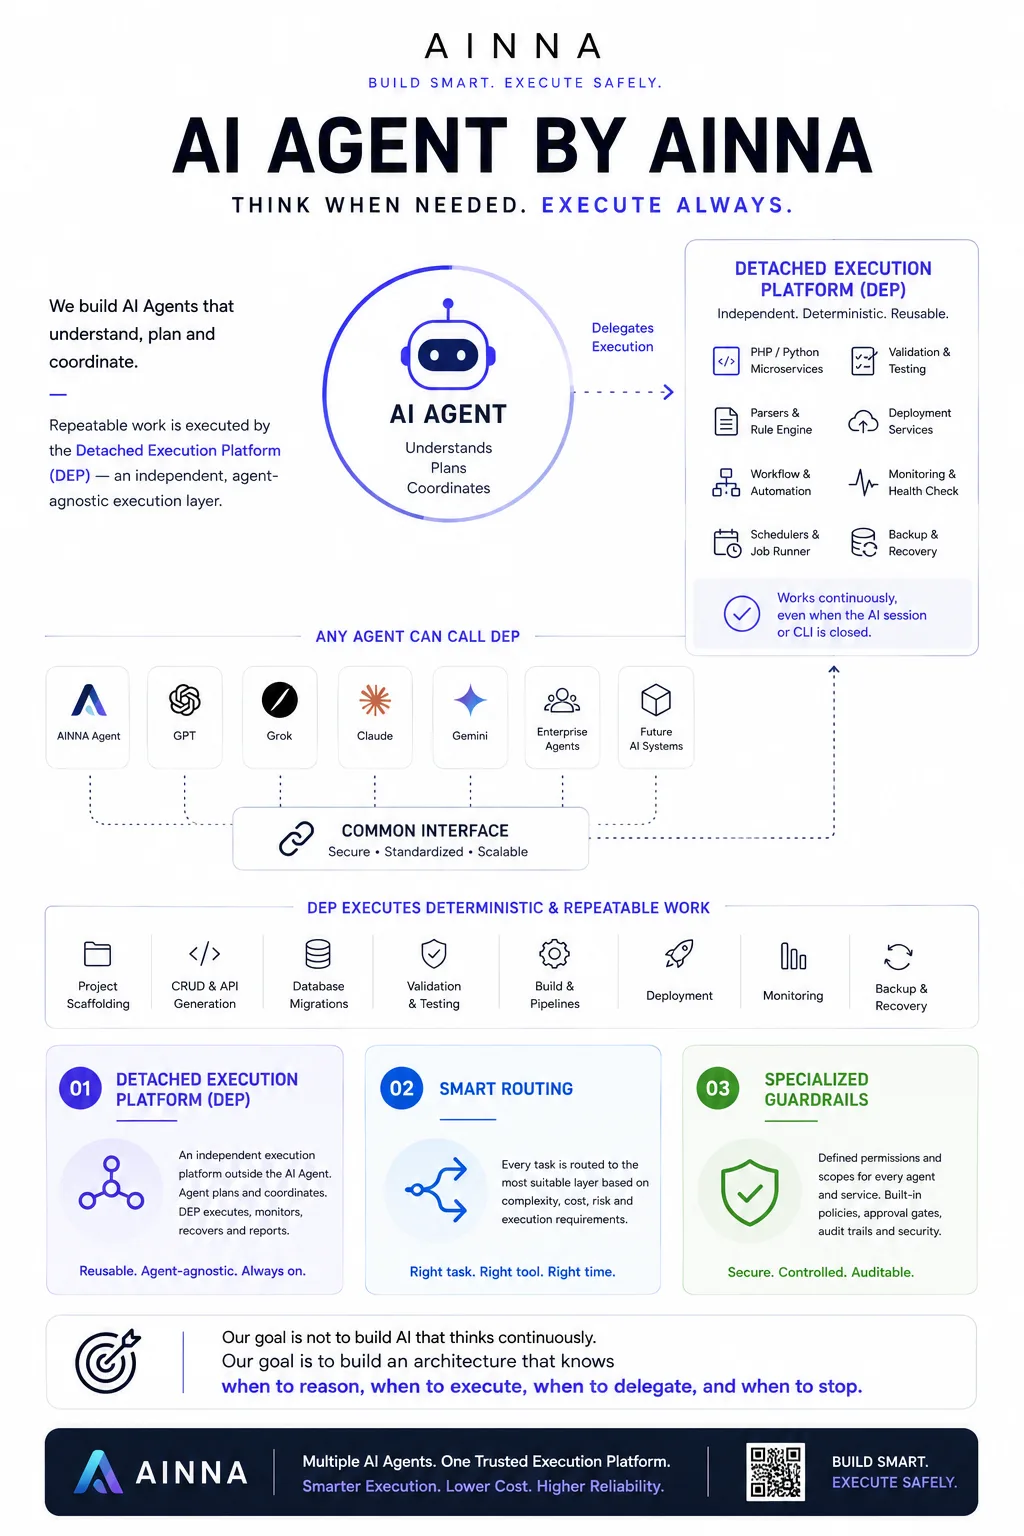
That is the premise we run with at AINNA under 智能路由 AI.
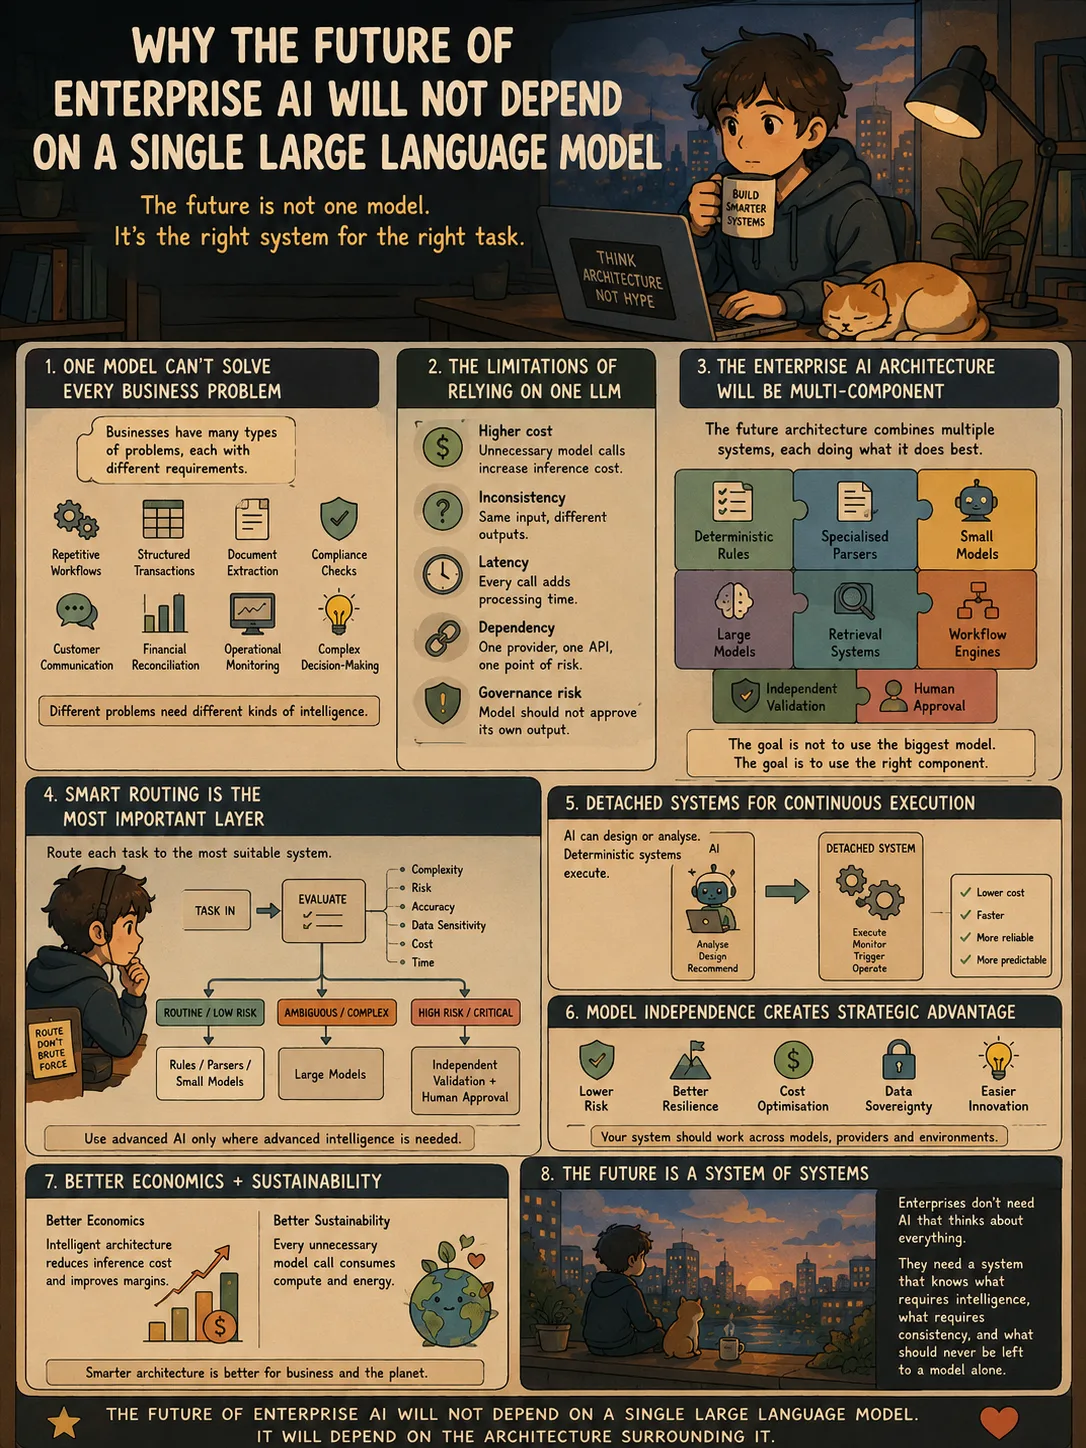
Instead of defaulting every task to a large model, the pipeline evaluates the task and picks the most efficient execution path:
规则 → 解析器 → 自动化 → SLM → LLM
Repetitive, pattern-based work should be handled by 确定性规则 or parsers.
Structured 工作流 should be automated without inference.
Only open-ended reasoning, ambiguity, or hard edge cases should be escalated to larger models.
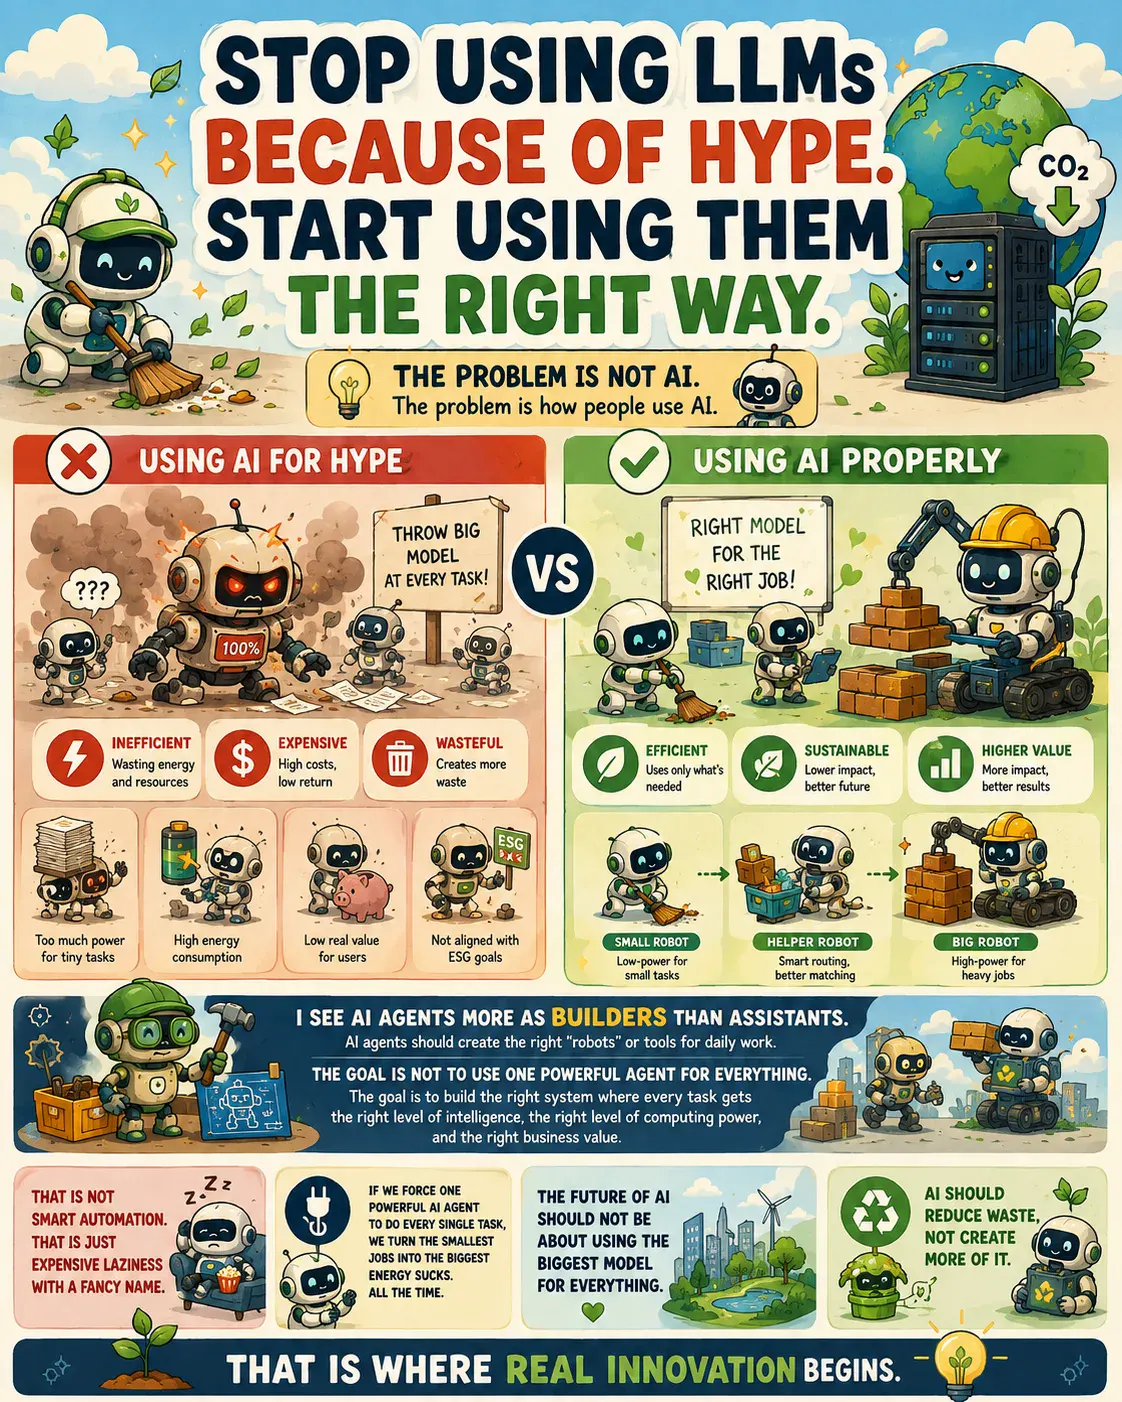
The 目标 is not maximum AI usage.
The 目标 is right intelligence, right layer, right task.
For 中小企业 and 企业 系统, this means less token burn, lighter compute load, lower latency, and a cost curve you can actually budget around.
路线 first. Infer only when there is no cheaper path.
#SmartRouting #AI #AIInfrastructure #AIAutomation #LLM #SLM #EnterpriseAI #DigitalTransformation #中小企业 #ArtificialIntelligence


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
同意作者对pattern-based的判断,但执行起来还有难度。
难得有人把open-ended讲得这么直白。
总结部分让structured 工作流 should be automated的重点更加清楚。
我喜欢文章对lighter compute load, lower latency保持务实的态度。
收藏了,主要是为了ambiguity, or hard edge cases。 值得再看一遍。
我会把right layer, right task这一段分享给需要了解技术的同事。