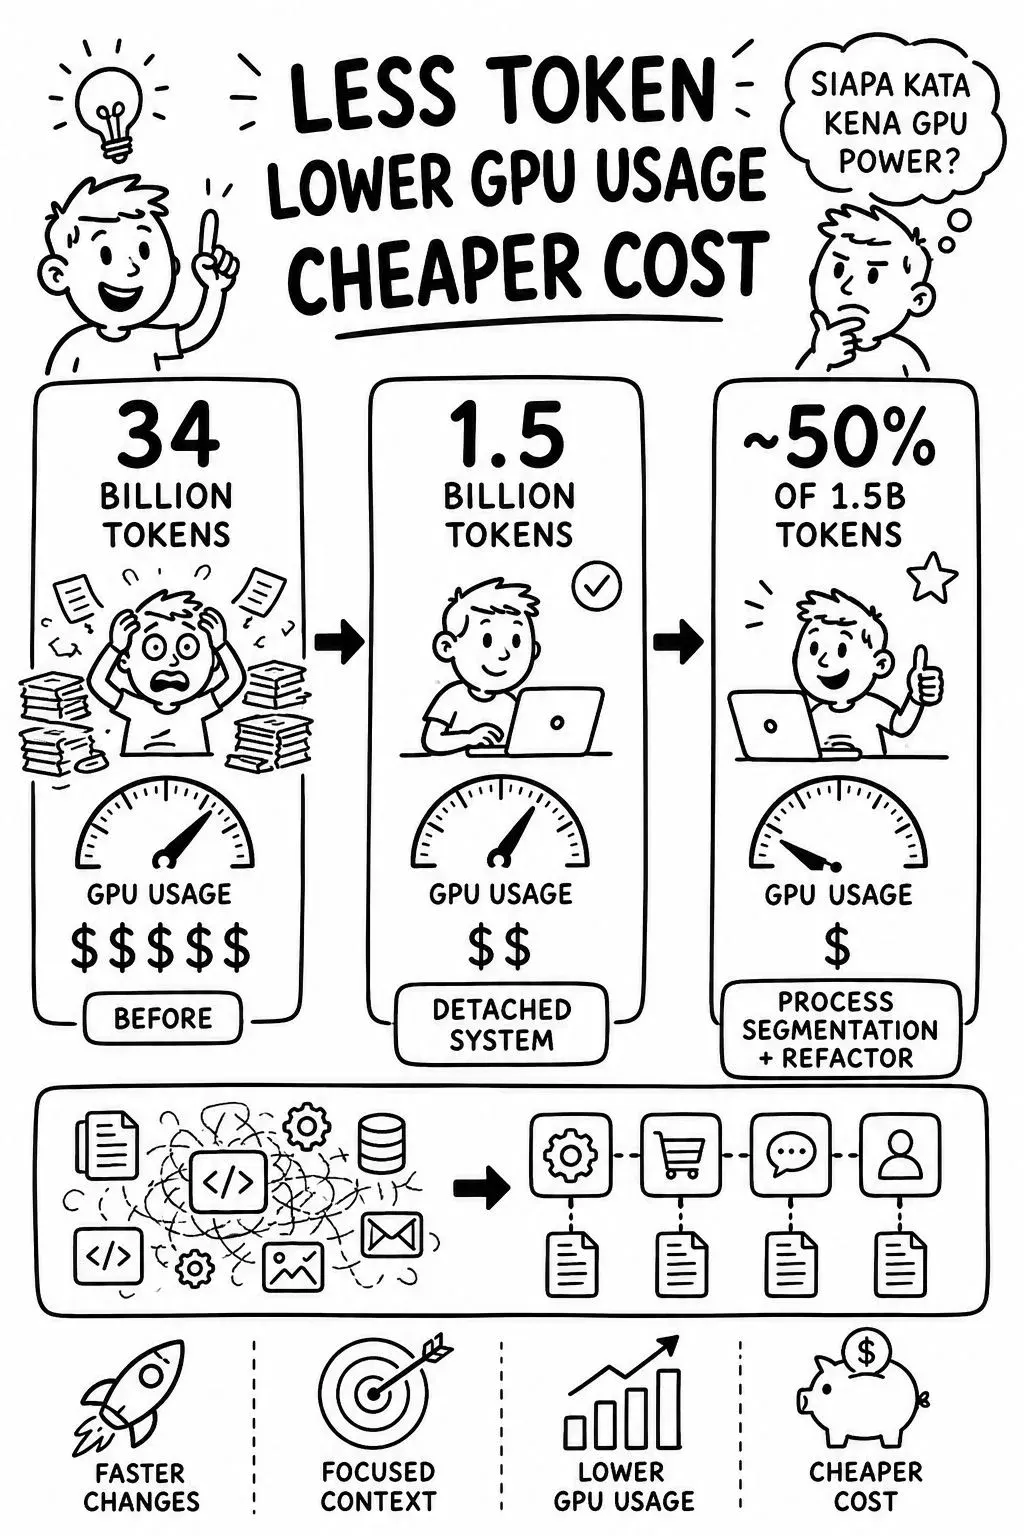
We started at 34 billion 令牌 across the 系统. After moving to a detached 系统 architecture, usage fell to around 1.5 billion. With process segmentation and modular refactoring, we cut that again by roughly 50% from 1.5 billion.
This is not prompt tuning. It is 系统 设计. Most AI cost is wasted because the model is forced to re-read the same domain, the same schemas, the same logic and the same 工作流 again and again for every small change.
But when the 系统 is detached and every process owns its own dictionary and contract, the AI only loads what it needs. Modify the payment flow? Pull the payment context. Modify order checking? Pull the order context. No full-系统 scan. No token bonfire.
This is where 中小企业 can win. AI should not be a privilege reserved for companies with giant servers and giant budgets. The future is not just bigger models. The future is 系统 that feed the model exactly what it needs, and nothing more.
Official 跨-网络 Resource


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
34读起来很清楚,也容易跟着理解。
难得有人把memory pressure, latency and burn讲得这么直白。
我喜欢文章对modify the payment flow保持务实的态度。
文章对pull the payment context的结论比较平衡,不只是强调好处。
我会把is not pro 1.5 billion这一段分享给需要了解技术的同事。