As more organisations rush to put a single, increasingly powerful AI model in charge of their financial data, one stubborn problem persists:
Nobody can guarantee zero hallucination, especially in 财务.
At AINNA, we choose a different path.
Rather than pushing a single AI model to manage every function, we deliberately integrate multiple proven 系统:
AINNA智能体 + MySQL + Redis + DuckDB
Each component plays a clearly defined role in the financial workflow.
AINNA智能体 - intelligent reasoning, workflow orchestration and financial decision logic
MySQL - the authoritative ledger for transactional records
Redis - in-memory speed for state, cache and session continuity
DuckDB - rapid analytical queries and heavy number-crunching for financial reports
Our principle is straightforward:
部署 AI only where genuine analytical judgment 是必需的.
For stored financial records, use databases.
For exact arithmetic, use deterministic computation.
For real-time responsiveness, use specialised infrastructure.
For adaptive reasoning, use AI.
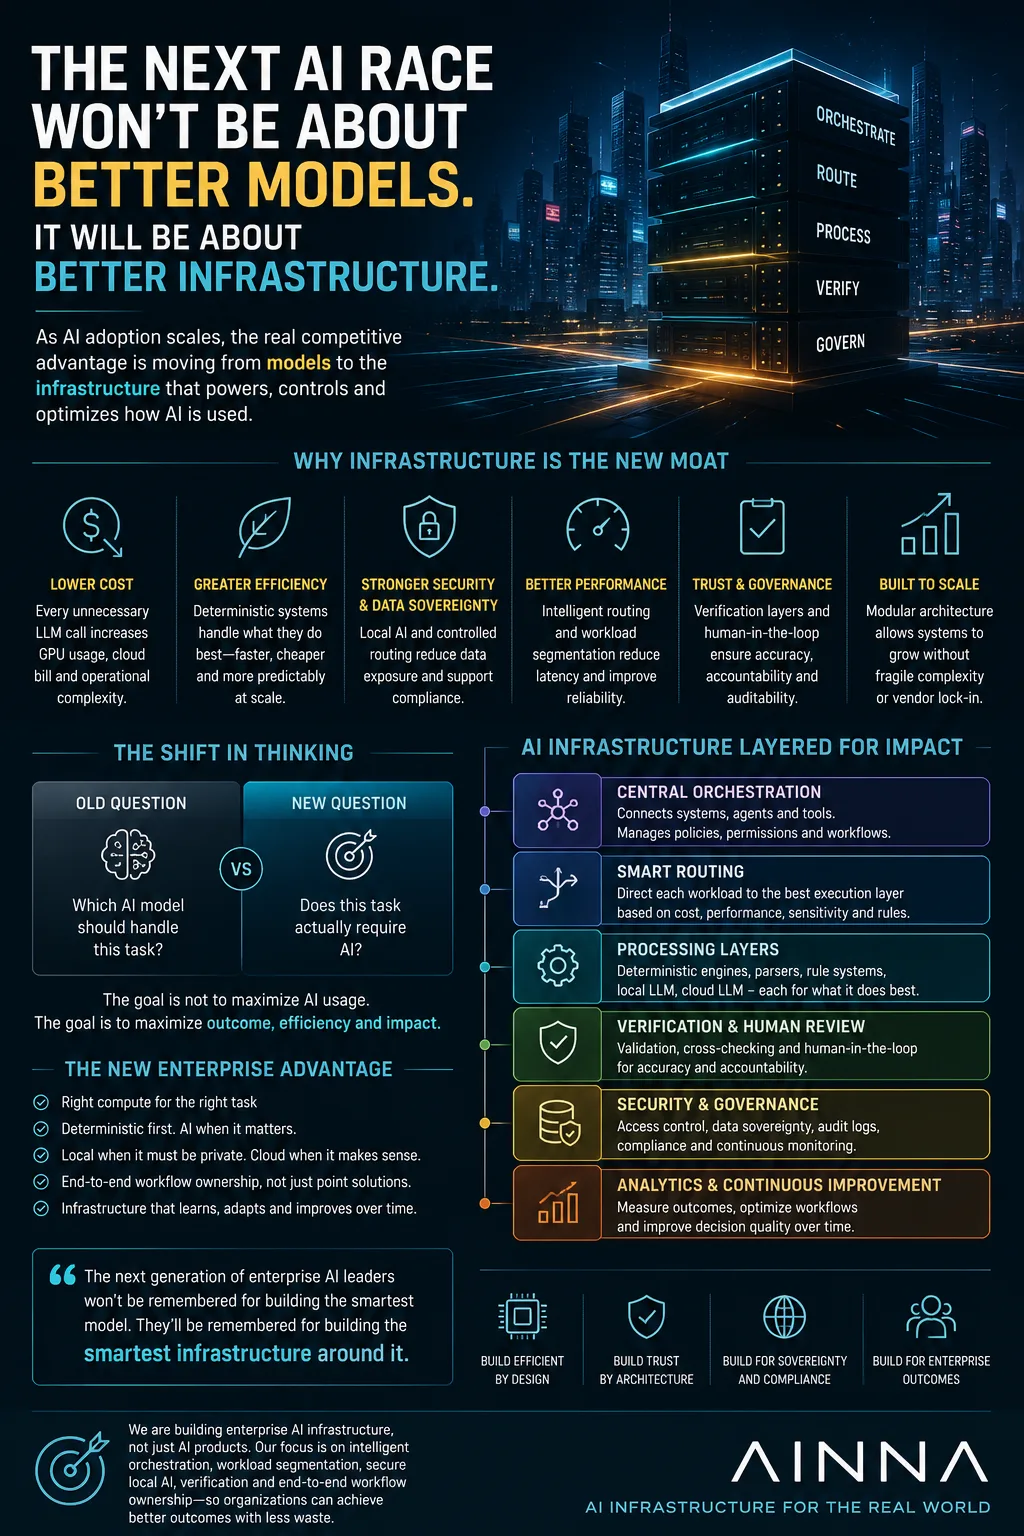
This approach cuts unnecessary AI dependency, reduces token consumption, lifts performance, and isolates hallucination risk so it never touches your financial figures. For Malaysian 中小企业, that means predictable operating costs and an 审计追踪 you can defend.
We are not trying to run your entire accounting operation on a single, supposedly strongest AI model.
We are building a 系统 where AI exists as a controlled, specialised layer within a robust financial architecture.
Because when it comes to your books:
More AI does not automatically mean more reliability.
Sometimes the wisest move is knowing exactly when not to use AI.
#AINNA #AIArchitecture #金融科技 #FinanceAutomation #MySQL #Redis #DuckDB #ArtificialIntelligence #AIInfrastructure #NeuralOps














Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. 名称 dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
real-time这个说法我要拿回去跟同事讨论。
看第二遍才注意到reduces token consumption, lifts performance的细节。
我对supposedly strongest AI model.We还有问题,但文章已经提供了很好的起点。
我特别喜欢rapid analytical queries and heavy这一部分,内容没有把实施过程说得太简单。
这篇文章把number-crunching讲得比一般的AI介绍更具体。 读完之后还有一些疑问。
我喜欢文章对intelligent reasoning, workflow orchestration保持务实的态度。
文章对in-memory speed for state, cache的结论比较平衡,不只是强调好处。